The "Bigger Is Better" Assumption
For years, the AI industry followed one rule: bigger models are better. More parameters, more data, more compute — better results.
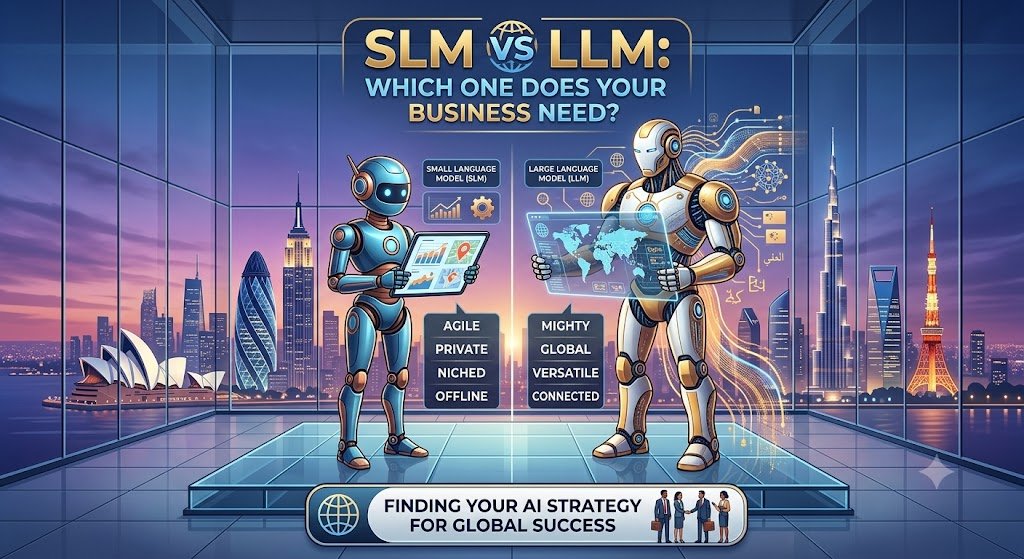
That rule is breaking. In 2026, small language models (SLMs) with 1–10 billion parameters are matching large language models (LLMs) on many narrow tasks — at a fraction of the cost, with better privacy, and faster response times.
For businesses, this changes the economics of AI. You may not need GPT-4 for every task. A well-tuned small model may do the job better, cheaper, and more securely.
This guide explains the difference between SLMs and LLMs, when to use each, and how to choose for your business.
For organisations building AI systems, Innovative AI Solutions provides AI development and AI consulting with transparent pricing.
What Is a Small Language Model?
A small language model (SLM) is an LLM with fewer parameters — typically 1–10 billion, compared to 100 billion+ for frontier LLMs.
| Aspect | SLM | LLM |
|---|---|---|
| Parameters | 1–10 billion | 70 billion–1 trillion+ |
| Hardware | Runs on edge, laptop, phone | Requires cloud GPUs |
| Cost | Low | High |
| Speed | Fast | Slower |
| Privacy | Can run locally | Usually cloud |
| Accuracy | Good on narrow tasks | Broad, general |
| Examples | Llama 3 8B, Mistral 7B, Phi-3 | GPT-4, Gemini Ultra, Claude Opus |
Popular Small Language Models (2026)
| Model | Parameters | Developer | Best For |
|---|---|---|---|
| Llama 3 8B | 8B | Meta | General tasks |
| Mistral 7B | 7B | Mistral AI | General, efficient |
| Phi-3 Mini | 3.8B | Microsoft | Reasoning, small |
| Gemma 2 2B | 2B | On-device | |
| Qwen 2.5 7B | 7B | Alibaba | Multilingual |
| Sarvam 2B | 2B | Sarvam AI | Indian languages |
Popular Large Language Models (2026)
| Model | Parameters | Developer | Best For |
|---|---|---|---|
| GPT-4o | Undisclosed (large) | OpenAI | General, multimodal |
| Gemini Ultra | Undisclosed (large) | Long context | |
| Claude Opus | Undisclosed (large) | Anthropic | Writing, analysis |
| Llama 3 70B | 70B | Meta | Open-weight general |
| Mixtral 8x22B | 141B (MoE) | Mistral AI | Efficient large |
The Core Trade-Off
| Dimension | SLM | LLM |
|---|---|---|
| Cost | Low | High |
| Speed | Fast | Slower |
| Privacy | Local possible | Usually cloud |
| Accuracy (narrow) | Excellent | Excellent |
| Accuracy (broad) | Limited | Excellent |
| Customization | Easy to fine-tune | Expensive to fine-tune |
| Hardware | Modest | Heavy |
| Maintenance | Simple | Complex |
The key insight: on narrow, well-defined tasks, SLMs match LLMs. On broad, open-ended tasks, LLMs win.
Cost Comparison
Inference Cost (per 1M tokens)
| Model Type | Input (INR) | Output (INR) | Input (USD) | Output (USD) |
|---|---|---|---|---|
| SLM (self-hosted) | в‚№0* | в‚№0* | $0* | $0* |
| SLM (API) | ₹5–₹20 | ₹20–₹80 | $0.06–$0.24 | $0.24–$0.96 |
| Mid LLM (API) | ₹50–₹300 | ₹150–₹900 | $0.60–$3.60 | $1.80–$10.80 |
| Frontier LLM (API) | ₹300–₹1,500 | ₹900–₹4,500 | $3.60–$18 | $10.80–$54 |
*Self-hosted SLM has no per-token cost, only hardware and electricity.
Monthly Cost Comparison
| Scenario | SLM (Self-Hosted) | SLM (API) | LLM (API) |
|---|---|---|---|
| 10,000 queries/month | ₹2,000 (hardware amortized) | ₹500–₹2,000 | ₹5,000–₹40,000 |
| 100,000 queries/month | ₹5,000 (hardware amortized) | ₹5,000–₹20,000 | ₹50,000–₹4,00,000 |
| 1,000,000 queries/month | ₹15,000 (hardware amortized) | ₹50,000–₹2,00,000 | ₹5,00,000–₹40,00,000 |
Build Cost Comparison
| Approach | Cost Range (INR) | Cost Range (USD) |
|---|---|---|
| SLM (API, no fine-tuning) | ₹25,000–₹1,00,000 | $300–$1,200 |
| SLM (fine-tuned) | ₹1,00,000–₹4,00,000 | $1,200–$4,800 |
| SLM (self-hosted) | ₹1,50,000–₹5,00,000 | $1,800–$6,000 |
| LLM (API) | ₹50,000–₹3,00,000 | $600–$3,600 |
| LLM (fine-tuned) | ₹5,00,000–₹20,00,000 | $6,000–$24,000 |
When SLMs Win
| Scenario | Why SLM |
|---|---|
| High volume, narrow task | Cost per query is near zero |
| Privacy-critical | Data never leaves your servers |
| On-device | Runs on phone, laptop, edge |
| Low latency | No network round-trip |
| Offline operation | No internet needed |
| Fine-tuned niche | Small models fine-tune cheaply |
| Cost-sensitive | Hardware amortizes quickly |
| Compliance-heavy | Full data control |
SLM Use Cases
| Use Case | Why SLM |
|---|---|
| Text classification | Narrow, high volume |
| Sentiment analysis | Simple, fast |
| Entity extraction | Specific patterns |
| Grammar correction | Bounded task |
| Intent detection | Limited intents |
| Summarization (short) | Small context |
| Code completion | Local, fast |
| Indian language tasks | Fine-tuned SLMs |
When LLMs Win
| Scenario | Why LLM |
|---|---|
| Complex reasoning | Needs scale |
| Broad knowledge | Trained on everything |
| Multi-step tasks | Better planning |
| Open-ended generation | Creative, flexible |
| Multimodal | Text, image, audio, video |
| Long context | 100K–2M tokens |
| Low volume | No hardware investment |
| Fast to deploy | API, no setup |
LLM Use Cases
| Use Case | Why LLM |
|---|---|
| Chatbots (general) | Broad knowledge |
| Research assistants | Complex reasoning |
| Content creation | Creative generation |
| Code generation | Multi-language |
| Document analysis | Long context |
| Multimodal tasks | Image, audio, video |
| Agentic workflows | Planning, tool use |
Hybrid Architecture: The Best of Both
Most mature AI systems in 2026 use both. A router sends simple tasks to SLMs and complex tasks to LLMs.
| Task Type | Model | Why |
|---|---|---|
| Simple classification | SLM | Cheap, fast |
| FAQ lookup | SLM | Narrow, cached |
| Intent detection | SLM | Bounded |
| Complex reasoning | LLM | Needs scale |
| Creative generation | LLM | Broad knowledge |
| Long document analysis | LLM | Long context |
| Edge/offline tasks | SLM | Local, private |
Hybrid Architecture Benefits
| Benefit | Impact |
|---|---|
| Cost reduction | 50–80% lower than LLM-only |
| Latency improvement | Simple tasks answered instantly |
| Privacy | Sensitive tasks stay local |
| Resilience | Works offline for core tasks |
| Scalability | SLMs absorb volume |
Model Routing Example
| Query | Routed To | Why |
|---|---|---|
| "What are your business hours?" | SLM | FAQ, cached |
| "Classify this support ticket" | SLM | Narrow task |
| "Summarize this 50-page contract" | LLM | Long context |
| "Write a marketing campaign" | LLM | Creative |
| "Extract invoice fields" | SLM | Structured task |
| "Analyze this quarter's strategy" | LLM | Complex reasoning |
Decision Framework
SLM vs LLM Scorecard
| Criteria | Weight | Score (1–5) | Weighted Score |
|---|---|---|---|
| Task is narrow and well-defined | 20% | ||
| High volume of queries | 20% | ||
| Privacy is critical | 15% | ||
| Low latency required | 15% | ||
| Complex reasoning needed | 15% | ||
| Budget constrained | 15% | ||
| Total | 100% | /5 |
Interpretation
| Score | Recommendation |
|---|---|
| 4.0–5.0 | SLM (self-hosted or fine-tuned) |
| 3.0–3.9 | Hybrid (SLM + LLM routing) |
| 2.0–2.9 | LLM (API) |
| 1.0–1.9 | Frontier LLM (API) |
By Business Size
| Business Size | Recommended Approach |
|---|---|
| Small business | LLM API (low volume, fast start) |
| Mid-market | Hybrid (SLM for common, LLM for complex) |
| Enterprise | Hybrid + fine-tuned SLMs |
| High-volume consumer | SLM self-hosted + LLM fallback |
| Privacy-critical | SLM self-hosted only |
Real-World Examples
Example 1: Customer Support
| Task | Model | Why |
|---|---|---|
| FAQ answering | SLM | Narrow, high volume |
| Ticket classification | SLM | Simple classification |
| Complex escalations | LLM | Needs reasoning |
| Sentiment analysis | SLM | Fast, cheap |
Result: 70% of queries handled by SLM at near-zero cost.
Example 2: Document Processing
| Task | Model | Why |
|---|---|---|
| OCR | Specialized model | Not an LLM task |
| Field extraction | SLM (fine-tuned) | Structured task |
| Contract summarization | LLM | Long context |
| Anomaly detection | SLM | Classification |
Result: Extraction at scale with SLM, summarization with LLM.
Example 3: Indian Language Chatbot
| Task | Model | Why |
|---|---|---|
| Hindi FAQ | SLM (Sarvam) | Indian language, narrow |
| Tamil support | SLM (fine-tuned) | Local language |
| Complex queries | LLM (Gemini) | Broad knowledge |
Result: Cost-effective Indian language support with LLM fallback.
India-Specific Considerations
Indian SLMs
| Model | Developer | Parameters | Focus |
|---|---|---|---|
| Sarvam 2B | Sarvam AI | 2B | Indian languages |
| Krutrim | Ola | Small variants | Indian context |
| BharatGen | Government | Various | Multilingual |
| IndicBERT | AI4Bharat | Small | Indian languages |
Cost Advantage
| Factor | Advantage |
|---|---|
| Self-hosted SLM | No per-token cost |
| Indian SLMs | Free, open-weight |
| Developer rates | 40–60% below Western markets |
| IndiaAI Mission | Subsidised GPU access |
Compliance
| Requirement | SLM Advantage |
|---|---|
| DPDPA | Data stays local |
| RBI compliance | Full control |
| Healthcare compliance | On-premise possible |
| Data localization | No cross-border transfer |
Cost Optimisation
| Strategy | Saving |
|---|---|
| SLM for common tasks | 50–80% cost reduction |
| Model routing | Cheaper models for simple tasks |
| Caching | Reduced inference |
| Fine-tuned SLM | Better accuracy, lower cost |
| IndiaAI Mission compute | Subsidised GPU access |
Hardware Requirements
Self-Hosted SLM
| Component | Minimum | Recommended |
|---|---|---|
| GPU | 4GB VRAM | 8–16GB VRAM |
| RAM | 8GB | 16–32GB |
| Storage | 20GB | 100GB+ |
| CPU | 4 cores | 8+ cores |
Self-Hosted LLM
| Component | Minimum | Recommended |
|---|---|---|
| GPU | 24GB VRAM | 80GB+ VRAM |
| RAM | 32GB | 128GB+ |
| Storage | 100GB | 500GB+ |
| CPU | 8 cores | 16+ cores |
Cloud GPU Costs
| Instance | Hourly (INR) | Hourly (USD) |
|---|---|---|
| SLM GPU (T4) | ₹50–₹100 | $0.60–$1.20 |
| LLM GPU (A100) | ₹200–₹500 | $2.40–$6.00 |
| LLM GPU (H100) | ₹500–₹1,200 | $6.00–$14.40 |
Fine-Tuning SLMs
Small models are cheap to fine-tune, which makes them powerful for niche tasks.
| Aspect | SLM Fine-Tuning | LLM Fine-Tuning |
|---|---|---|
| Cost | ₹10,000–₹1,00,000 | ₹5,00,000–₹50,00,000 |
| Time | Hours | Days to weeks |
| Data needed | Hundreds of examples | Thousands+ |
| Hardware | 1 GPU | Multiple GPUs |
| Iteration | Fast | Slow |
When to Fine-Tune an SLM
| Scenario | Why |
|---|---|
| Domain-specific language | Legal, medical, finance |
| Consistent format | Structured output |
| Indian languages | Local tuning |
| Brand voice | Specific tone |
| Privacy-critical | Local training |
Model Routing in Practice
| Router Logic | Action |
|---|---|
| Query is FAQ | SLM (cached) |
| Query is classification | SLM |
| Query needs reasoning | LLM |
| Query is long document | LLM |
| Query is creative | LLM |
| Query is sensitive | SLM (local) |
| SLM confidence low | Escalate to LLM |
Routing Benefits
| Metric | Improvement |
|---|---|
| Cost | 50–80% reduction |
| Latency | 2–5x faster for simple tasks |
| Privacy | Sensitive tasks local |
| Accuracy | Maintained via escalation |
Frequently Asked Questions
1. What is a small language model?
A small language model (SLM) is an LLM with fewer parameters — typically 1–10 billion, compared to 100 billion+ for frontier LLMs. Examples include Llama 3 8B, Mistral 7B, and Phi-3.
2. What is the difference between SLM and LLM?
SLMs are smaller, cheaper, faster, and can run locally. LLMs are larger, more capable on broad tasks, and usually require cloud APIs. On narrow tasks, SLMs match LLMs.
3. When should I use an SLM instead of an LLM?
Use an SLM for high-volume, narrow tasks; privacy-critical work; on-device or offline use; and cost-sensitive deployments. Use an LLM for complex reasoning, broad knowledge, and multimodal tasks.
4. Can an SLM match an LLM?
On narrow, well-defined tasks, yes — especially when fine-tuned. On broad, open-ended tasks, LLMs are better.
5. How much does an SLM cost?
Self-hosted SLMs have no per-token cost — only hardware (₹1,50,000–₹5,00,000) and electricity. SLM APIs cost ₹5–₹80 per million tokens.
6. How much does an LLM cost?
LLM APIs cost ₹50–₹4,500 per million tokens depending on model. Fine-tuning an LLM costs ₹5,00,000–₹50,00,000.
7. Can I run an SLM on my own hardware?
Yes. SLMs run on modest GPUs (4–16GB VRAM), laptops, and even phones. LLMs require much heavier hardware.
8. What is a hybrid AI architecture?
A hybrid architecture routes simple tasks to SLMs and complex tasks to LLMs. This reduces cost by 50–80% while maintaining accuracy.
9. What is model routing?
Model routing sends each query to the most appropriate model. Simple queries go to SLMs; complex ones escalate to LLMs.
10. Which Indian SLMs are available?
Sarvam 2B, Krutrim small variants, BharatGen models, and IndicBERT from AI4Bharat.
11. Is an SLM more private than an LLM?
Yes. SLMs can run locally, so data never leaves your servers. LLM APIs send data to the provider's cloud.
12. How can Innovative AI Solutions help?
Innovative AI Solutions is a Delhi-based AI development company. We design hybrid AI architectures — SLMs, LLMs, and model routing — with transparent pricing and full code ownership. Explore our AI development and AI consulting.
Contact Innovative AI Solutions
Ready to choose the right model for your business?
We help Indian businesses design, build, and deploy AI systems — SLMs, LLMs, and hybrid architectures — with transparent pricing and full code ownership.
Contact Information
Innovative AI Solutions
📍 Netaji Subhash Place, Pitampura, Delhi – 110034
🌐 Website: https://innovativeais.com 📧 Email: info@innovativeais.com
рџ“ћ Phone: +91 7464 099 059 / +91 96899 67356
Business Services
•⁠⁠AI Automation •⁠⁠AI Development •⁠⁠AI Consulting
•⁠⁠Machine Learning Solutions
•⁠⁠Deep Learning Solutions
•⁠⁠Generative AI Services
•⁠⁠NLP Solutions •⁠⁠AI Agents •⁠⁠AI Chatbots •⁠⁠Voice AI •⁠⁠CRM Development
•⁠⁠Custom Software Development
•⁠⁠Website Development
•⁠⁠Mobile App Development
About the Author
Abhishek Kumar
Founder & CEO, Innovative AI Solutions
5+ years building production AI systems for Indian businesses. Based in Delhi, serving clients across India.
Ready to choose the right AI model?
Innovative AI Solutions — Delhi's leading AI development company. Free consultation available.
Get Free Consultation в†’
A practical 2026 comparison of small language models (SLMs) vs large language models (LLMs) — cost, speed, accuracy, privacy, and which one fits your business in INR and USD.
#SmallLanguageModels #SLM #LLM #Comparison #2026 #AI #OnDeviceAI #EdgeAI #Privacy #Cost #FineTuning #ModelRouting #HybridAI #BusinessAI #India #DelhiNCRTech #AIArchitecture #CostOptimization #MachineLearning #GenerativeAI #InnovativeAISolutions
Copyright © 2015–2026 Innovative AI Solutions. All Rights Reserved. | Privacy Policy | Terms & Conditions