The Debate That Refuses to Die
Every few years, the software industry declares a winner in the microservices versus monolith debate. Microservices were going to replace monoliths. Then monoliths were going to replace microservices. Neither happened, because the debate was always framed incorrectly.
The real question is not which architecture is better. It is where complexity should live, and who should pay for it. Microservices distribute complexity across infrastructure and operations. Modular monoliths concentrate complexity within a well-structured codebase. Both can work. Both can fail.
The AI era adds new dimensions to this decision. AI-powered systems have characteristics that change the calculus: unpredictable latency from model inference, expensive compute resources, stateful context management, and the need to evolve rapidly as models and use cases change.
Indian engineering teams face this decision with additional constraints: smaller teams, cost sensitivity, and the practical reality that operational complexity has a real cost in talent and attention.
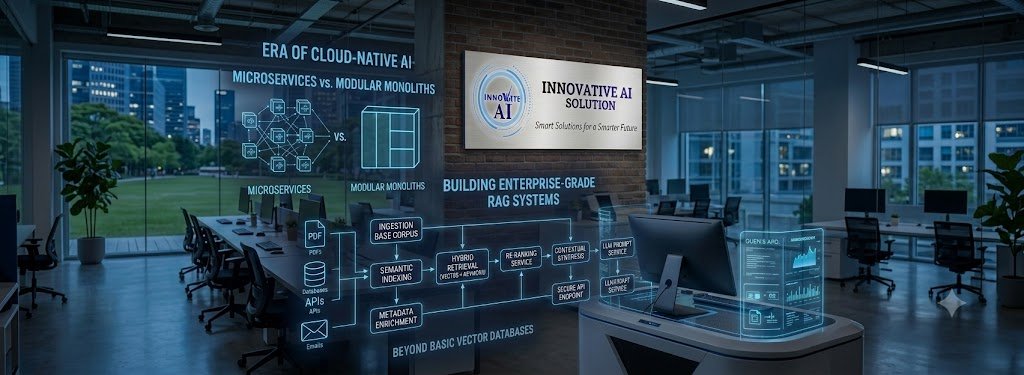
This guide provides a decision framework for microservices vs modular monoliths in the era of cloud-native AI. It covers the trade-offs that matter, the AI-specific considerations, the costs, and when each architecture wins.
What Each Architecture Actually Is
Modular Monolith
A single deployable unit with clearly defined internal modules that communicate through well-defined interfaces.
| Characteristic | Description |
|---|---|
| Deployment | Single deployable unit |
| Module boundaries | Enforced at code level |
| Communication | In-process function calls |
| Data | Typically single database, separate schemas |
| Scaling | Scale the whole application |
| Team structure | Teams own modules |
Microservices
Independently deployable services that communicate over a network.
| Characteristic | Description |
|---|---|
| Deployment | Independent services |
| Service boundaries | Enforced at network level |
| Communication | Network calls (HTTP, gRPC, messaging) |
| Data | Typically database per service |
| Scaling | Scale individual services |
| Team structure | Teams own services end-to-end |
The Core Difference
| Dimension | Modular Monolith | Microservices |
|---|---|---|
| Boundary enforcement | Code conventions, build tools | Network, deployment |
| Failure mode | One failure affects all | Isolated failures |
| Communication cost | Function call | Network call |
| Operational complexity | Low | High |
| Development complexity | Moderate | High |
| Team coordination | Code-level | Service contracts |
Why the AI Era Changes the Calculus
AI-Specific Characteristics
| Characteristic | Architecture Implication |
|---|---|
| Unpredictable latency | Model inference varies widely |
| Expensive compute | GPU resources need efficient use |
| Stateful context | Conversation and session state |
| Rapid evolution | Models and prompts change frequently |
| Multiple AI providers | Integration with external services |
| Observability needs | Tracing across AI pipeline steps |
How AI Systems Differ From Traditional Applications
| Traditional App | AI-Powered App |
|---|---|
| Deterministic responses | Probabilistic outputs |
| Consistent latency | Variable latency |
| Simple state | Complex context state |
| Stable logic | Evolving models and prompts |
| Predictable resource use | Bursty GPU demand |
The Latency Problem
AI inference latency is variable and can be high. In a microservices architecture, a request might traverse multiple services, each adding network latency. In a modular monolith, the same request stays in-process.
| Architecture | Typical Latency Overhead |
|---|---|
| Modular monolith | Minimal (in-process) |
| Microservices | 5–50ms per network hop |
| Multi-service AI pipeline | 50–200ms+ additional |
For AI applications where model inference already takes hundreds of milliseconds to seconds, additional network latency compounds the problem.
The GPU Resource Problem
GPU resources are expensive and often underutilised. In a microservices architecture, GPU-using services need careful resource management. In a modular monolith, GPU resources can be shared more efficiently within a single deployment.
When Microservices Make Sense
The Case for Microservices
| Situation | Why Microservices Help |
|---|---|
| Independent scaling needs | Scale GPU-heavy services separately |
| Different technology stacks | Python for ML, Node for API |
| Team autonomy at scale | Multiple teams, independent deployment |
| Fault isolation | One service failure does not bring down all |
| Independent release cycles | Deploy services without coordinating |
| Polyglot persistence | Different databases for different services |
AI-Specific Microservices Cases
| Use Case | Why Microservices Work |
|---|---|
| Separate model serving | GPU-heavy inference isolated from API |
| Multiple AI providers | Each provider integrated as a service |
| Different model types | Vision, language, speech as separate services |
| Async AI processing | Queue-based processing for long tasks |
| A/B testing models | Route traffic between model versions |
The Operational Cost of Microservices
| Cost Category | Impact |
|---|---|
| Infrastructure | More services, more resources |
| Observability | Distributed tracing required |
| Networking | Service mesh, API gateways |
| Deployment | CI/CD complexity increases |
| Debugging | Cross-service issues are harder |
| Team overhead | Coordination and contracts |
When Modular Monoliths Make Sense
The Case for Modular Monoliths
| Situation | Why Modular Monoliths Help |
|---|---|
| Small teams | Less operational overhead |
| Early-stage products | Faster iteration, simpler deployment |
| Unclear boundaries | Boundaries evolve as understanding grows |
| Latency-sensitive | In-process communication is faster |
| Cost-sensitive | Lower infrastructure cost |
| Simpler operations | One deployment, one codebase |
AI-Specific Modular Monolith Cases
| Use Case | Why Modular Monoliths Work |
|---|---|
| Early AI products | Rapid iteration matters more than scale |
| Single AI provider | No need for provider abstraction services |
| Tight latency requirements | In-process avoids network overhead |
| Small AI teams | Fewer services to maintain |
| Prototype to production | Simpler path from POC to deployment |
The Modular Monolith Discipline
A modular monolith is not a big ball of mud. It requires discipline:
| Practice | Purpose |
|---|---|
| Clear module boundaries | Define what each module owns |
| Explicit interfaces | Modules communicate through defined APIs |
| No cross-module database access | Each module owns its data |
| Enforced boundaries | Use build tools to prevent violations |
| Module-level testing | Test modules independently |
The Migration Path
A well-structured modular monolith can be migrated to microservices when needed. Services can be extracted module by module.
| Step | Action |
|---|---|
| 1 | Identify module with independent scaling needs |
| 2 | Extract module as separate service |
| 3 | Replace in-process calls with network calls |
| 4 | Deploy and monitor |
| 5 | Repeat as needed |
The Hybrid Approach
Why It Is Often the Best Answer
Most production systems are neither pure microservices nor pure monoliths. They are hybrids that use each architecture where it fits.
| Component | Architecture |
|---|---|
| Core application | Modular monolith |
| Model serving | Separate service |
| Async processing | Queue-based service |
| External integrations | Separate services |
The AI-Specific Hybrid
For AI-powered systems, a common pattern is:
text Modular monolith (core application) ├── Business logic modules ├── AI orchestration module └── Data access modules ↓ Separate services: ├── Model serving (GPU-optimised) ├── Vector database ├── Async processing queue └── External AI provider integrations This keeps the application logic cohesive while isolating resource-intensive and independently-scalable components.
What Each Architecture Costs in India
Infrastructure Cost Comparison
| Factor | Modular Monolith | Microservices |
|---|---|---|
| Compute | Lower (fewer resources) | Higher (more services) |
| Networking | Minimal | Significant (mesh, gateways) |
| Observability | Simpler tooling | Distributed tracing |
| Database | Single instance | Multiple instances |
| Ops tooling | Standard | Service mesh, orchestration |
Development Cost Comparison
| Factor | Modular Monolith | Microservices |
|---|---|---|
| Initial development | Lower | Higher |
| Deployment setup | Simple CI/CD | Complex pipeline |
| Testing | Simpler | Contract testing needed |
| Debugging | Local | Distributed |
| Onboarding | Faster | Slower |
Cost Benchmarks for AI Systems
| Architecture | Infrastructure (Monthly INR) | Infrastructure (Monthly USD) | Development Overhead |
|---|---|---|---|
| Modular monolith | ₹15,000–₹80,000 | $180–$960 | Baseline |
| Microservices (5–10 services) | ₹50,000–₹2,00,000 | $600–$2,400 | +30–50% |
| Hybrid | ₹30,000–₹1,20,000 | $360–$1,440 | +15–25% |
The Hidden Cost of Microservices
| Hidden Cost | Impact |
|---|---|
| Operational attention | Ongoing monitoring and maintenance |
| Debugging time | Cross-service issues take longer |
| Coordination overhead | Service contracts, versioning |
| Talent requirements | Distributed systems expertise |
| Tooling investment | Observability, service mesh |
For Indian startups and SMEs, these hidden costs often exceed the benefits of microservices.
Decision Framework
Architecture Selection Scorecard
| Criteria | Weight | Favours Monolith | Favours Microservices |
|---|---|---|---|
| Team size | 20% | Small (<10) | Large (>30) |
| Scaling requirements | 20% | Uniform | Independent |
| Latency sensitivity | 15% | High | Low |
| Technology diversity | 15% | Single stack | Multiple stacks |
| Deployment frequency | 10% | Coordinated | Independent |
| Operational capability | 10% | Limited | Strong |
| Budget | 10% | Constrained | Flexible |
Decision Matrix
| Your Situation | Recommended Architecture | Rationale |
|---|---|---|
| Startup, small team | Modular monolith | Speed, simplicity |
| Growing team, uniform scaling | Modular monolith | Simplicity with clear boundaries |
| AI product, early stage | Modular monolith | Iteration speed |
| AI product, GPU-intensive | Hybrid | Isolate model serving |
| Multiple AI providers | Hybrid | Services per provider |
| Large team, independent scaling | Microservices | Team autonomy, scaling |
| Regulated enterprise | Modular monolith or hybrid | Simplicity aids compliance |
| High-latency tolerance | Microservices | Network overhead acceptable |
AI-Specific Decision Factors
| Factor | Recommendation |
|---|---|
| Latency-critical AI | Modular monolith (in-process) |
| GPU-intensive inference | Separate model serving service |
| Multiple AI models | Hybrid |
| Async AI processing | Queue-based services |
| Rapid model iteration | Modular monolith or hybrid |
| Multiple AI providers | Hybrid |
Implementation Considerations
Building a Modular Monolith That Can Evolve
| Practice | Purpose |
|---|---|
| Define module boundaries clearly | Prevent coupling |
| Enforce boundaries with tooling | Prevent violations |
| Module-owned data | No cross-module database access |
| Explicit interfaces | Modules communicate through APIs |
| Independent testability | Modules can be tested in isolation |
Building Microservices That Stay Manageable
| Practice | Purpose |
|---|---|
| Start with few services | Avoid premature distribution |
| Clear service contracts | Versioned APIs |
| Centralised observability | Distributed tracing |
| Automated deployment | CI/CD per service |
| Service ownership | Teams own services |
The AI-Specific Concerns
| Concern | Architecture Implication |
|---|---|
| Model versioning | Separate model serving enables independent updates |
| Prompt management | Centralised or module-owned |
| Evaluation pipelines | Separate service for evaluation |
| Vector database | Shared or service-specific |
| Observability | Trace AI pipeline across components |
Frequently Asked Questions
1. Should I use microservices or a modular monolith for my AI system?
For most Indian startups and SMEs, a modular monolith is the better starting point. It offers faster iteration, lower operational overhead, and simpler deployment. Move to microservices (or hybrid) when you have independent scaling needs, multiple teams, or GPU-intensive workloads that benefit from isolation.
2. How does AI change the microservices vs monolith decision?
AI systems have unpredictable latency, expensive GPU compute, stateful context, and rapid evolution. These favour architectures that minimise network latency (modular monolith) and isolate resource-intensive components (hybrid with separate model serving).
3. What is a modular monolith?
A single deployable unit with clearly defined internal modules that communicate through well-defined interfaces. It is not a big ball of mud — it requires discipline around module boundaries, explicit interfaces, and module-owned data.
4. Can I migrate from a modular monolith to microservices later?
Yes. A well-structured modular monolith can be migrated module by module. Identify the module with independent scaling needs, extract it as a service, replace in-process calls with network calls, and repeat as needed.
5. How much do microservices cost compared to a monolith in India?
Microservices infrastructure costs 2–3x a modular monolith (₹50,000–₹2,00,000 monthly vs ₹15,000–₹80,000). Development overhead is 30–50% higher. Hybrid approaches cost 15–25% more than monoliths.
6. What is a hybrid architecture for AI systems?
A hybrid keeps business logic in a modular monolith while isolating resource-intensive components — model serving, vector databases, async processing — as separate services. This combines simplicity with efficient resource use.
7. When do microservices make sense for AI systems?
When you need independent scaling of GPU-heavy inference, multiple AI providers integrated separately, different model types as separate services, or async AI processing. Also when you have multiple teams needing deployment autonomy.
8. How does latency affect the architecture decision?
AI inference already takes hundreds of milliseconds to seconds. Each network hop in microservices adds 5–50ms. For latency-critical AI applications, in-process communication in a modular monolith avoids this overhead.
9. How do I enforce module boundaries in a modular monolith?
Use build tools to prevent cross-module imports, define explicit interfaces for module communication, ensure modules own their data, and test modules independently. Tools like ArchUnit (Java), import-linter (Python), and dependency-cruiser (JavaScript) help enforce boundaries.
10. What is the biggest mistake teams make with microservices?
Adopting microservices too early. Most teams do not need microservices until they have independent scaling requirements, multiple teams, or technology diversity. Premature distribution adds complexity without benefit.
11. How does a modular monolith handle GPU-intensive AI workloads?
It can share GPU resources efficiently within a single deployment. However, if GPU demand is bursty or needs independent scaling, extracting model serving as a separate service is better.
12. How can Innovative AI Solutions help?
Innovative AI Solutions is a Delhi-based AI development company that helps businesses choose and implement the right architecture for AI systems. We build modular monoliths, microservices, and hybrid architectures based on your scaling needs, team size, and budget. Our approach avoids premature distribution while planning for evolution. Learn more at https://innovativeais.com.
Contact Innovative AI Solutions
Ready to choose the right architecture for your AI system?
We help Indian businesses design and build architectures that match their scaling needs, team size, and budget.
Contact Information
Innovative AI Solutions
📍 Netaji Subhash Place, Pitampura, Delhi – 110034
🌐 Website: https://innovativeais.com 📧 Email: info@innovativeais.com
📞 Phone: +91 7464 099 059 / +91 96899 67356
Business Services
• AI Automation • AI Development • AI Consulting • Machine Learning Solutions • Deep Learning Solutions • Generative AI Services • NLP Solutions • AI Agents • AI Chatbots • Voice AI • CRM Development • Custom Software Development • Website Development • Mobile App Development
About the Author
Abhishek Kumar
Founder & CEO, Innovative AI Solutions
5+ years building production AI systems for Indian businesses. Based in Delhi, serving clients across India.
Ready to build AI solutions for your business?
Innovative AI Solutions — Delhi's leading AI development company. Free consultation available.
Get Free Consultation →
A practical 2026 decision framework for choosing between microservices and modular monoliths in AI-powered systems, with costs and trade-offs for Indian engineering teams.
#Microservices #ModularMonoliths #CloudNative #AIArchitecture #2026 #SoftwareArchitecture #DistributedSystems #EventDriven #ServiceMesh #Scalability #AISystems #BackendArchitecture #Monolith #ArchitectureDecision #India #DelhiNCRTech #StartupEngineering #EnterpriseEngineering #CloudNative #SystemDesign #TechIndia #DigitalProducts #AIInfrastructure #ArchitectureStrategy #InnovativeAISolutions
Copyright ©️ 2015–2026 Innovative AI Solutions. All Rights Reserved. | Privacy Policy | Terms & Conditions